Test robots.txt
The robots.txt decides which parts of a website search engines are allowed to retrieve. A typo locks out half the page in case of doubt - this often becomes visible weeks later. Here you can check what a rule actually does. No file yet? Create one here .
How it works
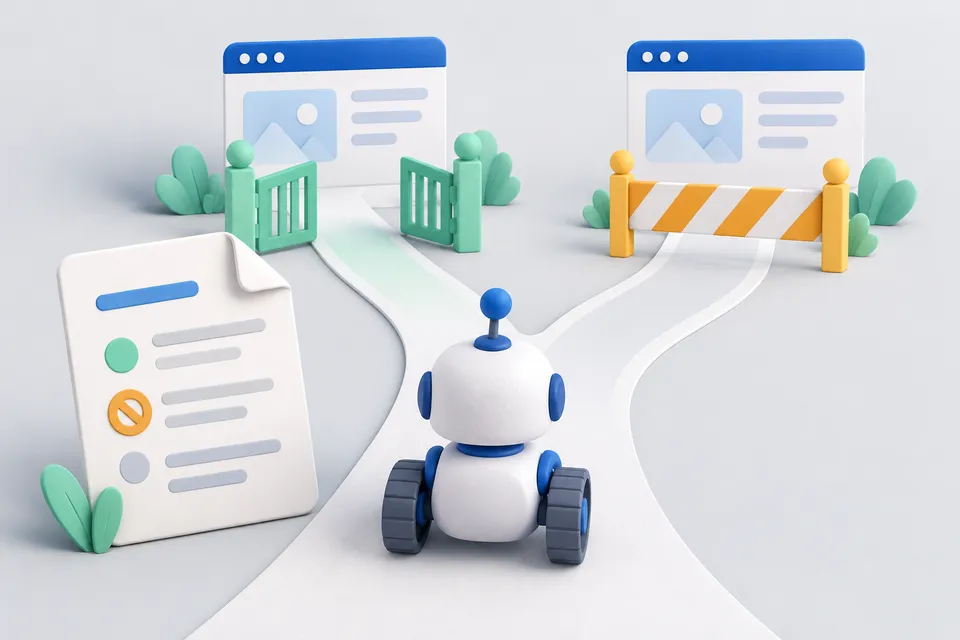
Which address can a bot visit?
- Load or paste robots.txt
- Select bot and addresses
- Checking permitted and blocked paths
1. Rules
2 Checking addresses
One address per line – complete or only the path from the slash.
3. Result
- erlaubt/admin/hilfe.htmlAllow: /admin/hilfe.html
- gesperrt/admin/geheim.htmlDisallow: /admin/
- gesperrt/produkte?sort=preisDisallow: /*?sort=
- erlaubt/impressumno rule applies
Specified sitemaps
- https://beispiel.de/sitemap.xml
How the evaluation works
It wins the longest true rule, not the one mentioned first. Disallow: /admin/ over Allow: /admin/hilfe.html, the help page is still allowed - the Allow rule is longer and therefore more accurate. If both are the same length, Allow wins. Google.
An asterisk stands for any character, a dollar sign at the end for the end of the address. Disallow: /*?sort= It blocks any address that is anywhere ?sort= contains.
For each crawler, only its own group applies. * – the rules of both groups are not added together.
Important: A lock in the robots.txt prevents this Retrieval, not necessarily appearing in the index. If a page does not appear in the search results, it belongs to noindex into the page – and this must not be blocked by robots.txt, otherwise no one reads it.
Other tools
From ‘Check and compare” and related categories. Free, with no sign-up.
Check a sitemap
Parse XML, find structural errors and check whether the listed URLs are reachable.
Open tool
URL comparison
Compare two pages side by side: scores, key metrics and every individual check.
Open tool
Google ranking check
How well does a page target a search term? Check titles, headings, body text, link text and technical requirements.
Open tool
Competition analysis
Compare your website with the ten results ahead of it and see what the leading pages do differently.
Open tool
Create .htaccess
Configure redirects, HTTPS, compression and access protection for Apache with a few clicks.
Open tool
Create a legal notice
Select a legal form and enter your details to create a German legal notice under section 5 DDG.
Open tool