Create robots.txt
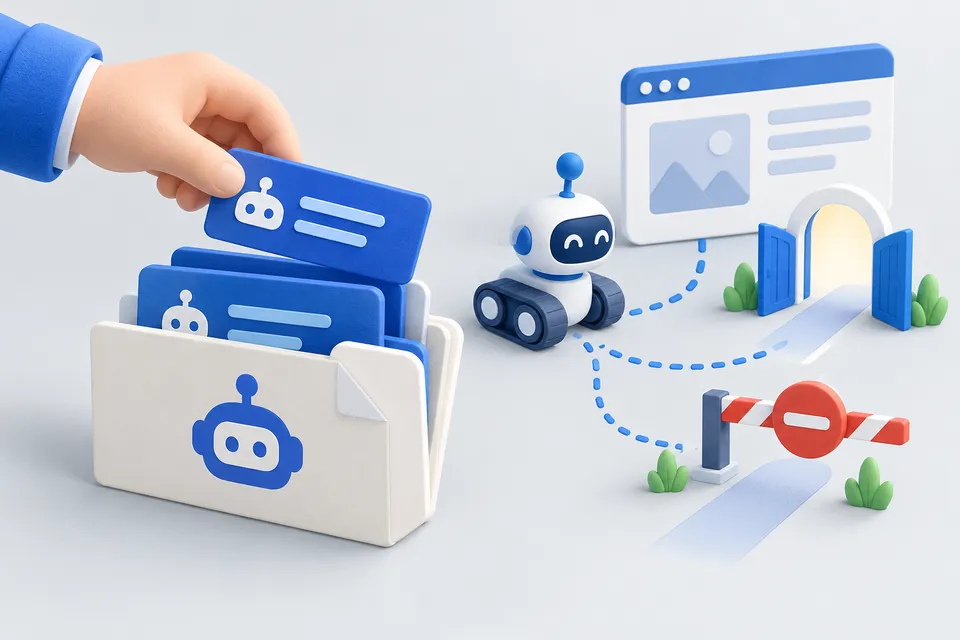
The robots.txt regulates which parts of a website search engines are allowed to retrieve. Here it is created by clicking - the preview grows when typing, nothing is sent to a server.
How it works
Setting the Ways for Website Bots
- Select the basic setting
- Determine blocks and exceptions
- robots.txt herunterladen
1 basic setting
One path per line. * stands for any sign.
Individual pages that should remain allowed despite blocking.
One per line. That's where the full address goes.
Seconds between two retrievals. Google ignores the statement, Bing Take note of them.
Result
User-agent: *
Disallow: /admin/
Disallow: /warenkorb
Disallow: /*?sort=

Sitemap: https://seitensicht.de/sitemap.xml
The file belongs unchanged in the root directory of the website, reachable at https://seitensicht.de/robots.txt.
What to look for
A lock in the robots.txt prevents this Retrieval, not necessarily appearing in the index: If a blocked page is linked elsewhere, it can still appear in the results without description text. noindex into the page itself – and that must not be blocked, otherwise no one reads it.
Never lock CSS or JavaScript files. Search engines represent the page; if they are missing, the page is rated incorrectly.
The file is publicly available. What it says here is a directions – no protection. Confidential areas belong behind a password, not in the robots.txt.
Finished? Then right away Testing against real addresses .
Other tools
From ‘For search engines” and related categories. Free, with no sign-up.
Create a sitemap
Paste URLs or scan your website, then download the finished XML file.
Open tool
Submit to search engines
Submit new pages directly to Bing, Yandex, Seznam, Naver and other search engines through IndexNow, with checks before submission.
Open tool
Website launch package
Fill in one form to create meta tags, Open Graph, schema markup, a favicon, robots.txt and a sitemap in one package.
Open tool
Create meta tags
Create titles, descriptions and preview images, with a preview of how Google displays the result.
Open tool
Create a legal notice
Select a legal form and enter your details to create a German legal notice under section 5 DDG.
Open tool
Check a sitemap
Parse XML, find structural errors and check whether the listed URLs are reachable.
Open tool